What reasoning buys
Strip away the product language and a reasoning model spends additional inference on an extended sequence of intermediate steps. That can help when the task is genuinely multi-step and the result can be checked: mathematics, algorithms, structured planning, or a constrained analysis.
The error is assuming that a hard problem is automatically a reasoning problem. Marketing is hard because it involves taste, uncertainty, context, and competing goals. More deliberation can make an answer more elaborate without making it more correct.
That is the impressive-looking tax: the team pays for a trace that resembles thought and then mistakes the trace for evidence that the model understood the business.
The illusion and the limit
The model's intermediate text is persuasive because it has the shape of a human explanation. It lists options, rejects them, and announces a conclusion. But a readable trace is still generated text; it is not an independent guarantee that the steps were causally necessary or that the premise was right.
Apple's "The Illusion of Thinking" paper provides a serious anchor for the skepticism. In its tested tasks, reasoning models experienced a sharp accuracy collapse past a complexity threshold. The paper interprets the result as evidence of hard limits in the apparent reasoning process, not proof that every reasoning model is worthless.
That nuance matters. The study has drawn methodological debate, as strong results should. The durable lesson is smaller and stronger: do not treat length of chain-of-thought as a proxy for truth.
Why marketing is different
Most marketing problems do not have a verifiable right answer. There is no answer key for the best positioning, audience segmentation, campaign narrative, or brand promise. A model can compare options, but it cannot deduce the one correct choice from the prompt alone.
Latency makes the default even harder to defend. Programmatic and paid-search decisions can live in millisecond windows. Personalization and send-time decisions can live in seconds. A deliberating model that returns after the decision window is closed is not a slower version of the same tool; it is the wrong tool for that path.
The answer is not to remove analysis. It is to define the decision contract and choose a tier that can meet it. Existing evidence, fast classification, and human judgment may outperform a longer synthetic trace.
Where it earns the premium
Reasoning can earn its place when three conditions line up: the task is genuinely complex, the stakes justify extra cost and latency, and the result has a checkable quality bar.
Examples include reconciling a complicated measurement model, debugging a multi-step data transformation, designing an evaluation plan, or analyzing a constrained experiment. Even there, use independent checks. A reasoning model is not its own verifier.
Use a fast model or deterministic code for retrieval, classification, formatting, and other work with a clear contract. The point is not that the expensive tier never helps. It is that the team should be able to explain why it is paying for it.
Tier the work
This is where the companion discipline of multi-model routing matters. The strategy is not "never reason." It is to use the smallest model that clears the quality bar in the time available, with a recorded route and a fallback.
Keep a representative evaluation set. Record model tier, policy version, latency, reviewer correction, escalation, and downstream outcome. If the reasoning response is cheaper to repair with a fast model, the premium is not paying for itself.
Reasoning models are a capability tier, not a worldview. Route by task, verify by consequence, and stop paying for a performance of thought when the work needs a decision instead.
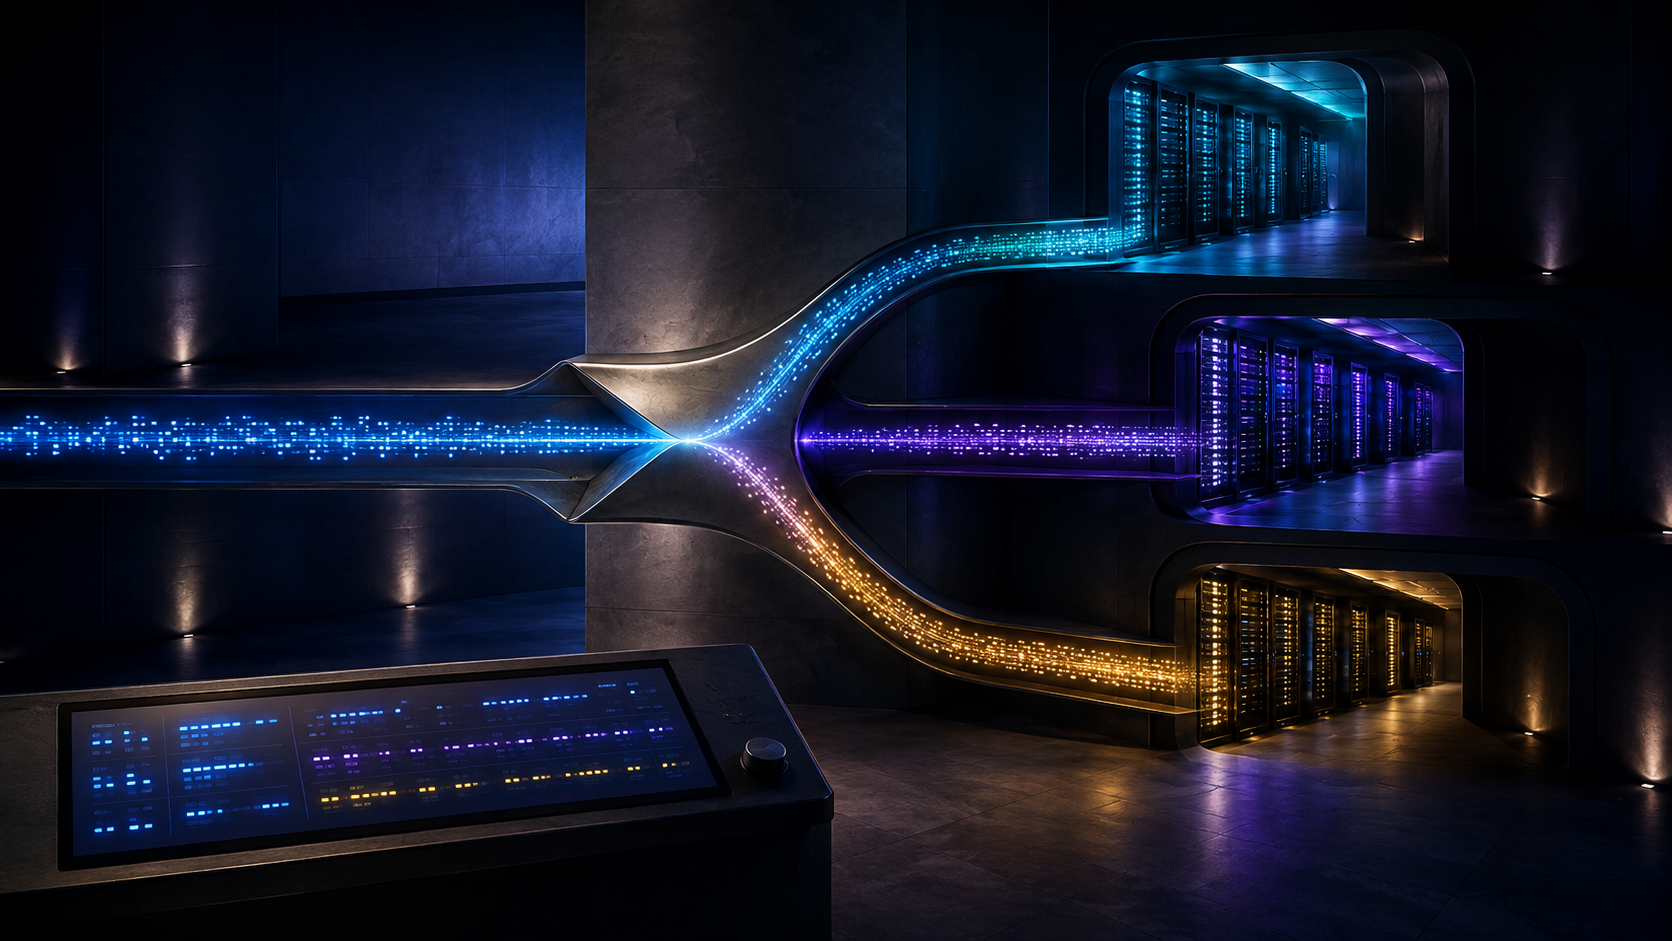
TASK-TO-TIER ROUTING
When does the premium earn its place?
01 / checkable
Use extra inference when the task has a right answer that can be reached and verified through multiple steps.